Portland’s $600 million biking plan

Portland’s $600 million biking plan

(this got stuck away in the ‘filed for later’ bin and I’m cleaning them out)

I’m not one that writes to reps often, but lately I sure have been.  Especially after Portland just passed a $600 million biking expansion plan in Portland.  Now I’m a fan of biking and exploring alternative transportation – but Oregon just forced a ballot measure vote on two new ‘Emergency’ tax increases to pay for basic services such as schools – both of which passed.  I have a really terrible time looking at people spending $600 million on these sorts of plans when basic services are in emergency mode.  But at any rate, there’s more to the story.

A few facts:
$600 million plan is a 20 year plan, and it is not actually funded yet.  It was just passed with funding to be figured out in the next 30-90 days.  The mayor is quoted as saying that his first thought on funding will be that once the big pipe project is finished, he’ll start diverting money from that project.  Problem is (as one writer pointed out), that money comes directly from water and sewage bills that were raised to nation-high levels to fund big pipe.  So, instead of dropping your taxes after big-pipe is fixed, your water bill would now start funding a bike project.

A few very notable and interesting quotes from sites:

“I propose that one way to help pay for these biking and pedestrian programs would be to license bikes with a yearly fee.  I think we could also increase public safety if the bikes also had to get a quick mechanical and safety check just like a car is required to pass.  It could also be used to ensure the rider has a proper helmet, lights for night riding, reflective gear, and other legally required safety equipment.  We have a lot of local bike shops in the area; and they could check out these bikes and issue these simple sticker permits that are attached to the bike like a yearly license plate sticker showing I’m up to date.  If the permits were numbered, it would also be a good way to track stolen bikes.  It would certainly help create and/or keep jobs at these local bike shops – especially in these tough times.”

(to the Portland Transportation commissioner) “Your choices as Transportation Commissioner openly, blatantly, and consistently discriminate against my use of TriMet’s bus system to get around.  As Transportation Commissioner, you have blamed buses for street conditions, when buses are but a small user of the road system.  You have openly, actively sought out regional transportation funds serving cities as diverse as Troutdale, Forest Grove and Sherwood to fund the Portland Streetcar – a development project that was somehow tied to transportation and thus raided money used to improve the bus system. And you demand TriMet pay $3 million a year to subsidize that system – that’s $3 million a year not going to regional transportation.

And then you have the gall to say we can’t afford another pet project. Remember: Portland extends from Raleigh Hills to Gresham. And it’s your job, as Mayor, to represent – and support – each one of those citizens. That means that guy living on S.E. 163rd Avenue is just as much a Portland resident as one downtown – and deserves an equal amount of investment (since you take an equal amount of taxes from them).

Now: Can we afford your bike plan – AND meet your promise to your constituents at the same time? Or are you playing favorites with your special interest groups again?”
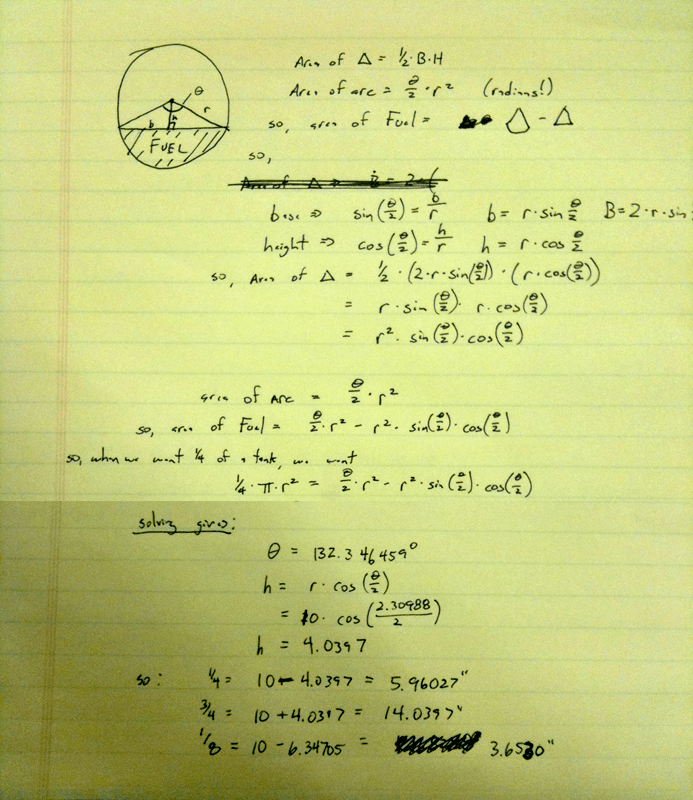
The key is MOV EDI, 0×9C5A203A

The key is MOV EDI, 0×9C5A203A

That’s the assembly instruction you need to unlock a secret ‘debug mode’ on AMD processors since the Athelon.  While you need to be in ring 0 to execute it; it did bring up some interesting possibilities of using the special debugging mode for reverse-engineering operation of the chip, accessing possible new features, or presenting a chink in the security armor.  So far, the security problems don’t seem to be probable, but if they cause undocumented resets/etc – they might be.

Anyway – interesting article.  Original posting here.

Cartalk conundrum

Cartalk conundrum

The guys from Car Talk have weekly puzzlers, but this question wasn’t a puzzler, but this came from a truck driver who called in.  He said (basically):

“I have big cylindrical tanks on my truck that lays sideways under the foot step.  Problem is that my gas gauge is broken.  I have a stick that I can put in vertically, so if the gas is at the 20″ mark on the stick, it’s full.  If the gas reaches the 10″ mark on the stick, the tank is clearly half full.  Where should I put the 1/4 and 3/4 marks on the stick?”

First you’d think they should be at 5″ and 15″, but that’s not right because the tank is round, which means the bottom and tops have less volume per inch of height.   Then you think this is a problem is an integration problem – which it can be – but the integration becomes extremely hairy.  Then, you find you can back up and use a geometric method (and when you can’t reduce anymore) use a numerical method to solve it.  So let’s get started!

We see that needing the actual volume of the cylinder is unimportant since you can solve this problem with just the cross-section – which is a circle.  What you want is a circle with a chord across it in which the volume between the chord and the outer wall is 1/4 the capacity of the circle.  So, you draw a diagram, and get started!

Unfortunately, you see that the equation becomes very difficult to solve analytically – and one must resort to numerical methods to get an actual solution.  I used the Mathematica online site, but you could easily use the Newton-Raphson method as well.  Whatever way you use, you find that he should mark the 1/4 tank line 5.96027 inches from the bottom of the stick.  3/4 and 1/8th values are also shown.

The value of this equation can quickly be used to calculate 1/8, 1/16, and all other desired fill marks by simply changing the 1/4 * pi * r^2 line whichever fraction you’d like. In fact, you can graph it to get any value:

Ignoring negative volumes, you see that the tank’s volume compared to it’s theta (roughly equivalent to height) forms a S curve, so that you can see that the height changes more rapidly w.r.t. volume when close to full/empty than in the middle – just like we’d expect.

So, that’s your answer.  Turns out, others have solved this since it’s a common problem with all kinds of other tanks (fuel oil, gas stations, etc).  Here and here are other solutions that verify the same process and confirm that the final equation is unsolvable analytically.

Another person pointed out that most semi’s have TWO tanks – one on each side – which are connected by a balancing flow connector.  So both tanks fill and empty evenly.  Even though this seems to mess up the problem, it actually does not.  In order to represent that situation, you simply multiply both sides by two (two tanks, two times the target volume) – which cancel each other out.  You could have ANY number of tanks connected like this and the answer is the same.

It also doesn’t matter how long the tank is either (so long as the tanks are the same size if you have more than one).  Finally, the theta angle you calculate doesn’t even depend on what radius of the tank!  So if you calculate the thetas for all the fill points, then you can calculate the 1/4 mark on ANY size tank.  Pretty nifty huh.

error LNK2019: unresolved external symbol _vmlsLn4

error LNK2019: unresolved external symbol _vmlsLn4

If you get this message while converting some code from compiling with the Intel Compiler over to using Visual Studio, then I have a solution for you:

error LNK2019: unresolved external symbol _vmlsLn4 referenced in function “BLAHBLAH”
fatal error LNK1120: 1 unresolved externals

Problem:
The Short Vector Math Library (SVML) which has the vmlsLn4() function is implemented in  svml_disp.lib.  Now this lib is usually only for the Intel Compiler’s use in vectorizing code but if someone used any of the SVML instructions, you can do the below trick to fix it.  See this article for more details about using SVML.

Solution:
1. Install the latest Intel Compiler (with Visual Studio links if it asks).  If that doesn’t come with the library you need, install Install Intel Parallel Studio as well. Between the two, you’ll get the svml_disp.lib you need.

2.  At the top of the .h/.cpp file that uses , declare this external:
extern
 “C” { __m128d vmldLn2(__m128d a); }

3. Go to your project settings, and for the library includes, add:
svml_disp.lib

4. In the ‘Additional Library Directories” box, add a path to wherever you installed the Intel compiler’s lib directory.  The default location is:
C:Program Files (x86)IntelCompiler11.167libia32

Hit F7 in Visual Studio and you should build like a champ and run just fine.

Bees can solve the traveling salesman problem

Bees can solve the traveling salesman problem

Researchers at Queen Mary, University of London and Royal Holloway have discovered that bees learn to fly the shortest possible route between flowers even if they discover the flowers in a different order. This ‘Travelling Salesman Problem’ often takes supercomputers days to solve, but Bees are now the first animals proven to do it. Computer-controlled artificial flowers were used to track the bee’s path and found they quickly learned the shortest route. Since a bee’s brain is only the size of a pinhead, researchers are hoping to identify the neural circuitry required and use that understanding to construct their own systems that rival the computational power of existing machines

Fascinating. A humbling reminder that despite the fact we consider computers near godlike in their abilities – there are solutions even the brightest minds can’t duplicate with a Turning-based machine. Or even reproduce at all.

Has often made me wonder if some day we’ll have a quantum or other non-Turing ‘co-processor’ with our current machines that is based on an architecture more suited to solving these types of difficult problems.

Earth shattering…

Earth shattering…

While it might not look like much, this software program called the Eureka machine uses standard video input, examines the behavior of a system, and with no previous knowledge of a system’s physics, kinetics, etc – it generates equations that accurately describe what is going on.

The program, from simple video input and a little massaging, it was able to generate the Hamiltonian equation for the difficult double-pendulum problem in about 30 minutes.  And a Lagrangian Equation that describes a double harmonic oscillator in another case – all in very short periods of time:


While this is very cool and to some degree just an expansion of what we have been able to do with neural net programming that ‘learns’ by trying out techniques and checking their results against reality – the ability for the program to generate equations takes this all a step further.To give an example of what this brings about – they recently applied the algorithm to some complex data collected in cell interaction.  While the scientists had struggled to make any meaning of the patterns, the program was able to come up with a formula that accurately described how these cells worked.  But this presented a new problem.  While the equation seemed to match exactly what was going on, the scientists who fed the data couldn’t figure out what physical components the variables the equation related too. They made the decision NOT to publish the equation in any papers with the accurate modeling equation because they didn’t actually understand how the equation modeled the system. While not unsurprising from an program that simply generates an equation from data; its the first time that these computers might actually be out-matching us for models of systems.  However, since they are unfettered by making the actual variables equate to real-world  phenomenon – they are free to generate equations who’s variables aren’t necessarily based on the underlying physical phenomenon.  THIS is the interesting part.It seems (rightly) that just modeling the situation isn’t sufficient to say you understanding it.  Does understanding of a phenomenon require the understanding of the underlying principles?  Should it? Sure, you might be able to come up with an equation that models what’s going on for the cases you have, but without understanding the principles behind it, you’re just putting your faith in the equations generated.  But is this what we do today?

I was taught since 6th grade science class that every scientific principle was only one repeatable converse case away from being refuted at any time.  History is full of such events – including the most deeply held ones such as Newton’s laws of motion. Depending on the size scale of use, they either work very well, or in the quantum/astrophysical realms – fall apart completely.  Those rules have been getting ‘touch-ups’ for years.  While Newton certainly isn’t categorically wrong – it’s clear we didn’t (and still don’t) have all the corners fleshed out.

So we find the crux of the matter -why shouldn’t the equations generated by this program be any more deserving of our trust than Newton’s?  I’d say the key lies in several ways: mostly in the requirement for rigorous review, numerous experimentally repeatable verifications, and apparently that the equation needs to be explainable with principles and terms that we DO understand.  The first part is very understandable.  No scientific statement worth it’s salt should be accepted without lots of peer review, repetition of the experiment by others in different conditions, public discussion, and confirmation via different methods.  This program required user intervention to get a balance between absolute accuracy and ‘simplicity’.  Which means it had to go through numerous iterations and a little bit of pre-known knowledge to get it to generate equations that corresponded to principles we understand. This implies it could generate different equations for the same phenomenon.  More on this later…

But the second reason, and the one the jury appears to be out on, appears that one needs to be able to explain WHY the equation works, or at least be based on terms we do understand.  In other words, just pulling the ‘answer’ out of the back of the book isn’t real understanding.  The right answer doesn’t seem to be sufficient by itself for science to classify as real knowledge.  For science, we also apparently need to be able to explain why it’s right too.  Only then can we actually say we have a decent understanding of something.

The unanswered question is if that requirement of being built on understood principles needlessly inhibits us.  What if we just ‘went with the flow’ and let machines like this generate those horribly difficult equations for us?  What would that look like/imply?  The equations that the software could generated didn’t always correspond to previously known/modeled phenomenon – and needed to be ‘guided’ by the user to answers in the form they wanted.  But this implies the computer in other circumstances might be revealing a different *kind* of thinking that we could backtrace?  What if those equations are just like another ‘culture’ or ‘language’ that sees the same reality in a different, but no less valid, way that we could explore and understand? I think that could be an interesting discussion for another entry.

This instance reminds us that there are very important philosophical principles behind what is considered scientifically known and not.  Principles that have real and interesting effects; and depending on when/where you lived, there were/are very different requirements for what is considered knowledge.

In case you’re interested, philosophically, this question of what is knowing is called Epistomology – and might be worth a look.  (Is my philosophy undergrad work showing?)